
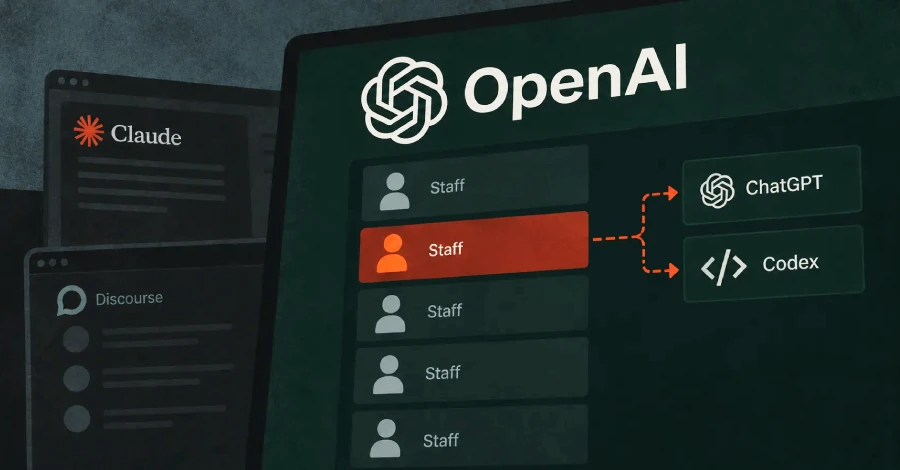
A trio of security researchers at Hacktron demonstrated this week that Anthropic’s Claude Opus 5 can serve as a force multiplier for vulnerability chaining. Using the AI model to guide their methodology, they chained a forum flaw with a login bypass to take over the ChatGPT and Codex accounts of several OpenAI employees, then pivoted from there into an internal OpenAI code repository. The research was conducted as responsible disclosure, and the findings have been shared with OpenAI.
The technique itself — using a capable reasoning model to identify how two independent weaknesses connect into a chain — points toward a broader shift in offensive security. What once required an experienced researcher to mentally map across authentication flows and application logic can now be assisted by an AI that holds the entire attack surface in context simultaneously. The researchers described Claude Opus 5 as “the first model that actually narrows the gap between what a junior and a senior researcher can find in a limited window.” OpenAI has not disclosed whether the vulnerabilities have been fully patched.